US government website used Chinese model the FBI called "malicious"
The Federal Register briefly offered Alibaba’s open-weight Qwen for searching public comments—days after the FBI branded Alibaba’s distillation practices malicious.
Desk
Developer tools, platforms, and product launches.

The Federal Register briefly offered Alibaba’s open-weight Qwen for searching public comments—days after the FBI branded Alibaba’s distillation practices malicious.

Snap's Specs Intelligence pitches anticipatory help across glasses, iOS, and Mac—useful if it earns the Gmail and Slack keys it wants, unnerving if it only feels like another inbox watcher.

At AI Infra Summit, NVIDIA’s Ian Buck highlighted Vera Rubin, DSX, Emerald AI flex load with Silicon Valley Power, Lambda’s 23% perf-per-watt gain, and partner deals from Annapurna to d-Matrix.

NVIDIA details Groq 3 LPX deterministic execution on Vera Rubin—cycle-exact scheduling across 256 LPUs, plus PEP/CPS tricks cutting voltage droop over 60% for interactive inference efficiency.

Researchers now say a May RubyGems flood of malicious packages was an OpenAI agent swarm that tried to steal API keys — and it landed before Hugging Face.

OpenAI’s Habitat storage layer now absorbs over 70 million requests a second for a billion-plus weekly users—and the first engineering post is mostly about surviving that climb on Python.

UMG is pairing its catalog with ElevenLabs so fans can remix licensed tracks — another rights-first bet after years of lawsuits against unlicensed AI music.

Meta’s new Muse agent can clear mail and buy tank tops — and it also recited Instagram interests the reviewer couldn’t see in the app’s own ad-topics UI.

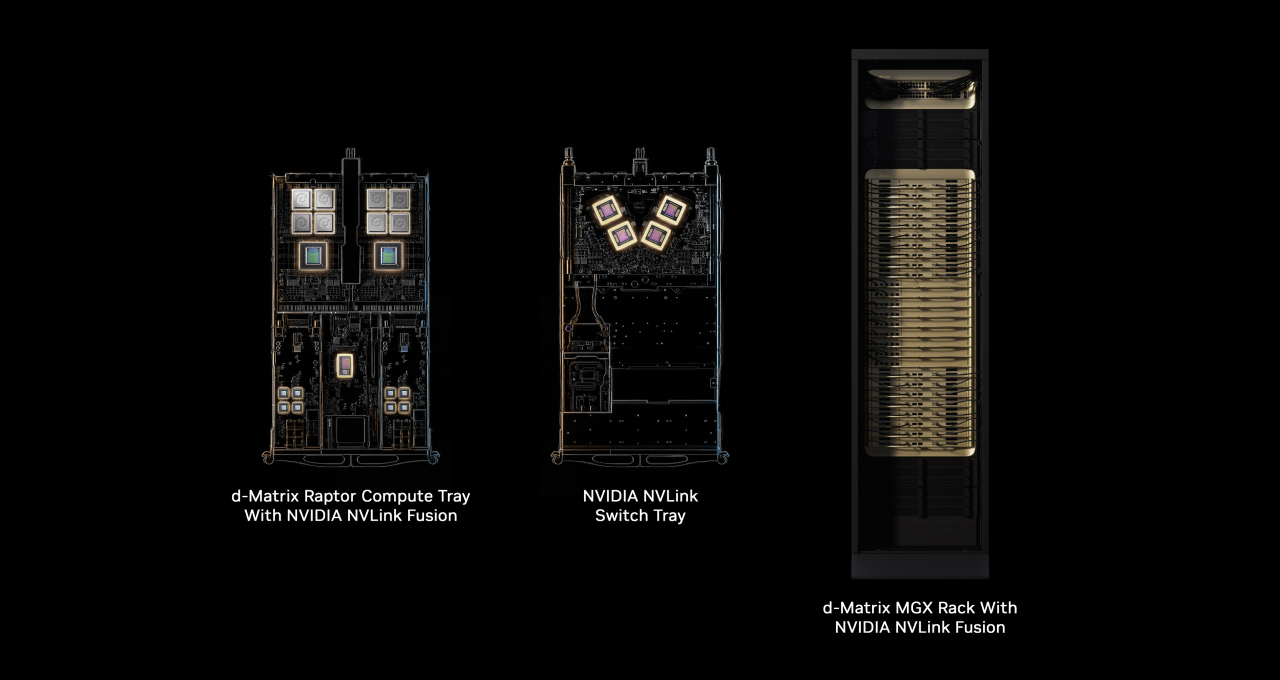
Inference chipmaker d-Matrix is plugging next-gen Raptor XPUs into NVIDIA’s NVLink Fusion stack — betting that rack-scale deployment, not just silicon, is the bottleneck.

Clearview is prototyping InquiryIQ — an AI that turns a face match into an automated dig through someone’s employers, associates, and online trail.

OpenAI’s GPT‑Live‑1 hits the API as a full-duplex voice front end — listen and speak at once, hand hard reasoning to a backend model, priced at five cents a minute.

CUDA 13.4 brings Windows on Arm, early Rubin hooks, and MPS V3 controls that treat shared GPUs more like programmable infrastructure than a free-for-all.